0:43:31
Tarun Garg - Design Django models such that your future self will thank you 👋
Published October 22, 2021
This video features Tarun Garg at DjangoCon Europe 2022 in Porto, Portugal.
Handling Django in highly concurrent & scale environment by Tarun Garg
Django is very good for getting things started & get going, but when it gets thrown into a highly concurrent & high scale environment then real issues start coming up, and you are often left with your head-scratching as to what is happening & how to deal with it; this talk will discuss some of the issues around concurrency & scale in Django & how did we handle it.
Tarun Garg presents practical ways to make Django applications behave better under high concurrency and scale, focusing on four recurring problems. For slow Django admin pagination, he compares replacing expensive counts with a dummy value, timing out counts, using PostgreSQL statistics, and using `EXPLAIN` estimates, while noting the trade-offs in accuracy and latency. He recommends namespaced admin search instead of applying every search field to every query, versioning cached Django-model keys when model definitions change, and using `save(update_fields=[...])` to prevent stale objects from overwriting unrelated updates; locking remains appropriate when concurrent processes update the same field.
Summarised automatically from the transcript.
Automatically transcribed, so expect mistakes in names and technical terms.
The feeling of being on stage after two and a half years of lockdown is unparalleled. I can't imagine how much I miss this. Uh hi everyone, my name is Tarun and I'm from India. I work there as an engineering manager at one of the startups in India, uh ScottStech. It's in a B2B space startup, so you might not have heard a lot about it. Coming to the talk, the title of my talk is Handling Django. In a highly scalable and concurrent environment. I know the title might sound a little bit clickbaity, but I hope that the content that's coming up your way will make it worthy. If anything, feel free to leave me a feedback on Twitter. My Twitter handle is in the bottom right by Tarun underscore Gak2.
Without further ado, let's get started. What is this talk about? Before going into there, I'll just give a fair bit of warning that uh there's a lot of content that I wanted to cover in this talk, and I have a limited time, so I'll speak a little bit quicker and Due to I being a non-native English speaker, you might miss out on a few words. So if you have anything you wanted to discuss with me, feel free to catch me outside uh the auditorium or on Slack. I'll be happy to assist So this talk basically is an I've been working in Django since last six years. So this talk basically encompasses some of the common scalability and concurrency challenges that I saw on Django. Everyone f everyone was facing the same issues. Literally everyone solved it in their own ways.
This talk is just an amulgation of everything that I have read. I've implemented at work. And in last six years, the major part of it has been working with Django 1. 8 and up and uh Postgres 13. We internally and in process of upgrading from Django to Uh at our org right now. So it might be that some of those things that I discussed here might have been fixed in the newer versions. And if those have been, I'll be happy to learn more about it With that in mind, let's get started with the first theme. Uh the first theme we have is Django admin pagination. So, uh before I go anything beyond, I want to make it explicit that Django admin is By far
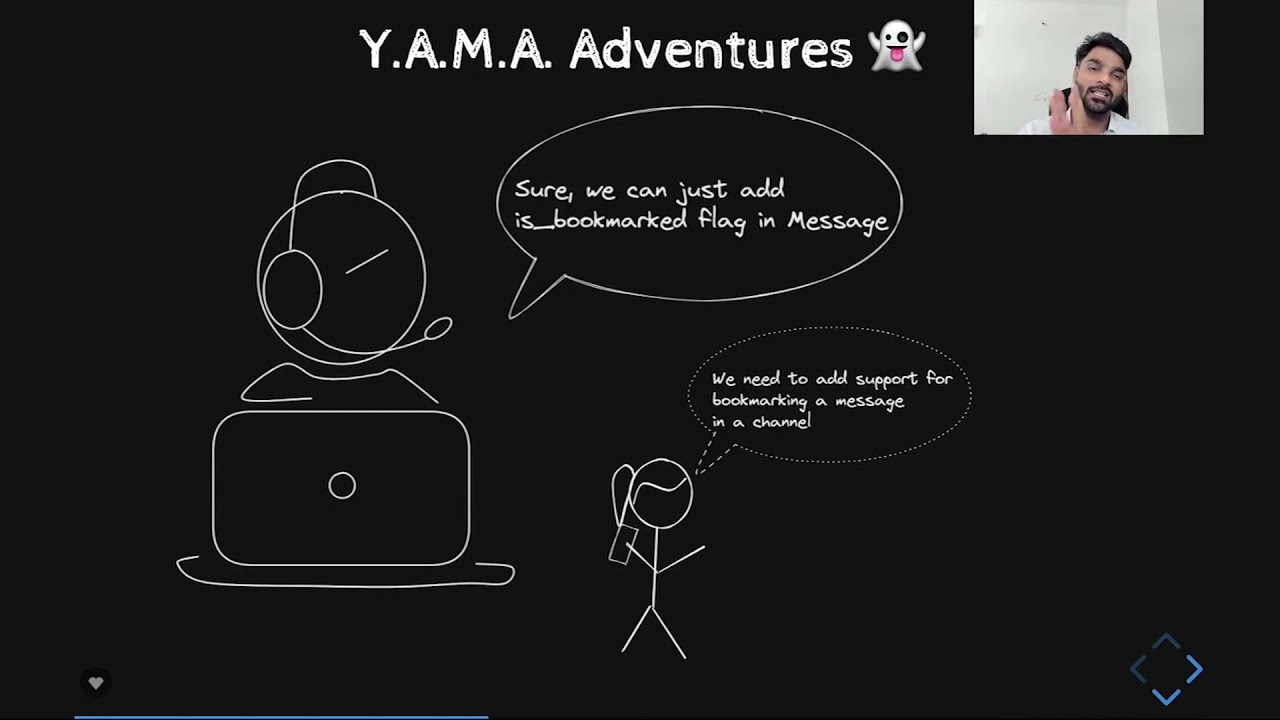
my best Django feature out there. It makes it so easy to just create an Ecrude uh application on the go. Uh it makes it very easy to get things started. I So much love it that I hate it. Uh that I hate the developers behind it, the mind behind it. That how did they come up with the idea and the design? And I'm so intrigued by it, all the capabilities that it it provides. So, uh talking about Django Adrian pagination, let's start with an example. Uh suppose you are trying to build a food ordering app, you have an order model there. Order has a reference ID uh and your support professionals wants to use see the all those orders. So you register a Django admin uh for the order
Now as your scale keeps on growing up uh you receive millions of orders and now when your support professionals open Uh the Django admin. This is the kind of pagination that Django provides by default, which is an offset-based pagination uh where you see one, two, three, four, which are the page numbers, and then you see the total count of records, which is 10 million records and each page has a certain amounts. As you might be already knowing, that offset-based pagination is kind of slow because of that limit offset problem that you need to traverse the whole thing. But Even if you load the first page in the Django admin, it still kind of takes time to load. Now we figure out we are like why is it taking time to load? I I'm not going into 100 page, I'm just still on the first page.
My why my first page is taking time to load. That's when we started debugging it. That why does my first page in the admin when you know my records grew in large in number was slow We figured out using Django debug toolbar there they are essentially two queries that are running. These are the main queries that are running. There were a lot of authentication and all the other meta queries that those were running. But these were the majorly the two queries that was running. One was Selecting the count of the whole order which was with you see the 10 million orders and another was just selecting the first hand out of it And counting the whole 10 million orders was taking uh two seconds of the time and rest of them are taking sub ten milliseconds of the time
So we figure that this is the problem that we have, that it is time to get the count of the whole table, and since that table is large, the count Getting the count uh takes time and that's why the page is stuck. And we then figure out that what is the ways that query being happening in the Django? Uh so Django has something called as page in it, where uh they have this count property where they say Samp. object list. count and if attribute error or something, then they'll just count the object list in case you are trying to build your own Django admin. So this is the count query that was happening uh behind the scenes, and we are like, oh, now this is the problems problem that we have that since the count is happening and count is taking time, how do I improve it?
First solution that came to our mind is we have that count uh cache property in Django. Why don't I just patch it and create it Very dumb page editor where I just return some random value out of it. So the count query is gone, problem is gone, problem solved. Right? There's no count query, there is no nothing of that sort It worked, it really did work. There was no count query happening again. Uh it was very dumb, it was very quick. But as with everything You create in software, there are pros and cons of each solution. So let's discuss pros and cons of this one. Pros were that no more count queries, and hence blazing fast first page of the admin Dumb and very fast and easy to reason about
uh implement, but the cons was UX was kind of compromised Because even if we have less than 1 million rows or 10 million rows or 100 million rows, it will return just return the dump page header. Right? So you do this user experience was not the best out there. And in reality, it was dump, right? And we should be able to do better. That's when we come to our next solution, which was best effort basis, uh, where we say, hey, I have the dump, but what if So the premise that we begin with that the count is taking too long. But what if there is a table where count where the count does not take too long? Where you know maybe you have 100k rows or 200k rows where the count doesn't take too long. I I should be able to do better there instead of bigger table.
So that's where we uh uh come about this best of word basis where we say that From the database, if you can get the count within 300 milliseconds, get the count from the database. If not, kill the database query and return the dumb value. What does the Django Code look like for that? This is the code that looks like where we say that for this particular statement that you are executing, set the statement time out to 300 MS Try to get the count. If you don't get the count, return the dumb value. So now on the best effort basis, if we are able to get within 300 ms, well and good. If not, return the dump But the problem is that worst case here is still 300 ms or 100 ms or whatever value you choose your application to be, and we have not removed the dumbness
entirely. And we were using Postgres as a database. So this led to our more research around what we can do more with the Postgres as a database along with Django So we read that Postgres has a nice blog post about how do you count rows effectively in Postgres, where Postgres what essentially does is it maintains a stat stable. Where it stores a statistics around your tables. So and under those statistics, it also stores the number of rows that you have in that statistics table. So we said why can't I use it? Uh so that's what we do. We said that hey uh can I get the estimated counts from Postgres catalog statistics If yes, well and good. If no, go back to the best effort, basis
it out. So now we have diversified our uh solution in a way that We are trying to uh improve uh per bit by bit. Where previously we had only the dump solution, then we did best effort basis. Then we went into Postgres uh catalog or system tables, getting the count from them. It worked, and this is what the code for that looks like, where we say that uh from the Postgres catalog class, which is PG class. Get the rail tuples, which is the number of rows. If you can get the tuples, well and good. If not, go the best of our basis route. This worked and from getting the number of rows from Postgres catalog table was some milliseconds latency.
It worked, but as with everything, there were pros and cons of this as well. One obvious probe was there was a good trade-off between accuracy and latency, that we were able to accurately predict something because our Postgres has this catalog or statistics table, and latency was also reduced The probability of reaching to the dumb value, which is 99999, is reduced. The cost for it, it is it does not work where we have filters applied Because how Postgres does is whenever you insert uh a row into uh the table, it updates the sets table that I have in your row. Whenever you delete it, It updates, it does not update in real time. There's something called as vacuum and analyze and that uh background processing that Postgres does. So this is where
It gets tricky that might not be suitable for smaller tables because that vacuum and analyze process is dependent on the number of changes you have in table. Postgres has a whole uh algorithm for it Or where analyze is run with a lesser frequency, which relates to the smaller table problem there. So this was the problem, then the main problem was that it doesn't work when we are filters applied Uh what if you have a Django page where you have a filters and you apply those filters and then it errors out because uh you can't get the count with the filters Still dumb value problem. That's when we reached to the fourth solution where we said that okay, uh, I cannot get from PG class as well, I cannot get from uh database as well directly What if I get an estimated count from the database using something called as explain in Postgres?
So for the uninitiated, what is explain? Explain is Postgres way of When Postgres engine runs a query, it tries to estimate how much data it will return. Based on that estimate, it actually runs the query. So, first step is that estimation, and then it actually runs the query. So we said, why can't I? Get that count from that estimation itself versus returning the dumb value, right? So that's where you so see here that in that flow chart, if you can't get within 300 MS, please get estimated count using explain. So that's the fourth solution uh we came about. And the code for that in Django uh looks something like this: where I just say that cursor. execute Explain format in JSON
the query and get the plan number flows. I guess in Django 3, I'm not sure about the exact version There is a native support for XPN where you can get XPLAN results by just doing dot XPLAN after the after writing your ORM query. Uh but since we were using a older Django at that time, I just did this where cursor. execute explain format JSON. So now with that uh You can get your estimator count from PG catalog or run some approximation queries to get that count result, which was you know really the problematic thing when you were loading the first page. There are pros and cons of this as well. Better trade-off than the previous solution between accuracy and latency. The probability of reaching value to the dumb value is reduced the most
The con of this is getting the count of rows using XPLAN is probabilistic because what Postgres is doing it it is probabilistically trying to guess how many rows it will return. And it's depend on a whole lot of things internally on Postgres, which is most common value list in Postgres and things like that. Uh that Postgres stores in in order to get to that explain results Might not be suitable for analyze with lesser frequency because how does Postgres probabilistically estimate it Uh using that analyze iterance constantly on your tables. It tries to create an histogram of values on your tables constantly If you have five values, for example, if you have something called a status, failed past, uh running, it try to create whenever it runs an analyze, it tries to create a histogram of the
of that that how many values are in past, how many values are in Failed, how many values are in running, which is all probabilistic on to be honest. So might not be suitable where you know that histogram creation is not running as frequently as you would wish to be Which led to our own observation that the solutions that we discussed problem is not entirely solved by any of the solution because what we are doing is we are Instead of getting a deterministic count, we are getting a probabilistic count right now. There exists some more sophisticated solutions that we want to try out in the future, but for now, for us, probabilistic count worked But one of the solutions that we can explore in future is hyperlog, which is something that Reddit use for their account.
I know, which is something for CITES data folks use for their accounts. You can cache those count results as well, but in caching the problem occurs that what if you have a filter supplied? How much do you cache? And what frequency do you update the cache? You can do parallelization to get the count values async using something async or await or something of that sort. Or you can get away with uh offset-based pagination and just move forward with the cursor-based pagination if that works for you. Then you have the count query problem resolved automatically. So, this is uh all I wanted to discuss in Django Admin Page Ination that how do you uh get from the uh place where you are unable to load the first page because of that count query?
How do you optimize that count query uh bit by bit? With that, uh wanted to move to next thing, which is uh Django admin text search. Uh I walk I I'll walk you through this using a story. Uh in this story, there is a developer, there is a support professional at the other end The developer said that hey, I am creating this admin page for orders. Can you tell me how you want to search for orders? Support professional comes and says, I think search by order reference ID should suffice. You create a search by order reference ID using search fields that Django provides. Developers come and say, Hey, do you need anything else? Support professional says, I sometimes want to search by username as well.
Okay, well and good. Pretty easy to do in Django. You just create another thing in search fields. Then support professional says, hey, maybe I want to search from last name, first name, and full name as well Cool, uh you create insert those things into uh search fields. Developer said, Are you sure about this? This is it, this is all you need But support professional says actually sometimes customer asks us with payment reference ID as well. So you will have to insert payment reference ID as well Cool, not a big deal for a Django developer because Django is awesome and I think I have a spelling mistake here, but in any case. Uh you you you insert that payment reference ID into search field What happens next is that search professional says that hey, my search is not working. Why is the search not working?
Is exactly what we are going to discuss in this particular theme. Django search fields are fantastic, but the problem begins when there are too many of that. And there are too many of that in our example. There was first name, last name, email, payment reference ID, order reference ID, whatnot. Why does this why is it a problemistic? Because Django has no idea to know what the user is searching for. So it creates a huge query Which is odd with all the search fields, which is inefficient. So, what does that what do I mean by that? When you search on that particular Django admin where you have a lot of search fields This is the kind of query that you get where you say select star from orders orders where reference ID like this search term
or Email like this third term or first name like this term or last name and when you have a lot of Rs your database gives up It it cannot use indexes, it can it does not use indexes because or by definition is that you have to do multiple uh uh you go to multiple tables, you have to search on multiple fields anyway. So it says if I have to search on multiple fields I might as well go to a disk directly and search for it. And as soon as it gets to disk, it it it slows down a lot So, uh we figured out that if the user wants to search by email or reference ID, there's no other reason to search by any other field. So if you are a support professional You get a ticket and you want to search by order reference ID. You just want to search by order reference ID.
There's no why why I am searching with the first name also, last name also, full name as well. Right? If I want to search by email, I just want to search by email Why am I searching by the first name last way last name as well? So we just need to provide a namespace search versus whole full text search that is provided by Django search field by default Or a group of fields then search that namespace versus searching everything which is the default default behavior uh right uh default behavior So we said that maybe instead of uh having the one search field which searches everything, what if I have different different filters namespaced by a use case? So I have it filter namespace by user, I have filter namespace by payments, I have filter namespace by order reference ID.
So that I know when I I would know in the code that where is that search coming from and I'll just execute that search on that. What does that look like in Django? It looks something like this where uh you know you have a reference ID and you you get the query set of ID You might say that hey, list filters are just exactly for that. Why can't you just use list filters? Because in case of emails, uh first name, last name, those are free from text A, if you use list firm, the list will be too huge. B there will be repeated entries. How do you deal with it? C uh you can definitely use something like select two or something of uh those things to you know optimize your list filters that way. But we felt that this is a much easier uh way to go about it than to go that route where you'll have to deal with the duplicates, you'll have to deal with the
uh Uh long list you will have to deal with uh the full text search and all of those things. Uh so yeah, this this was this was this what this theme was about. That how do you go about Optimizing uh your Django admin text search when you have just single search field. You don't want to plug in Elasticsearch just as of yet because you're not sure whether Elasticsearch this is the exact use of Elasticsearch or not. My database should be able to handle it. Because it's not really a full-text search when you know that hey, I want to search on this field. Full-text searches where you don't know what you want to search on. You're just searching in the wild trying to figure out if there exists something of that sort. With that, uh we'll move to our next theme, uh, which is caching Django models.
Uh I'll not go lit in much detail about what cache is because time limited, but I hope everyone here knows that cache primarily has two operations: one is cache set, one is cache get So, how does cache set happen in Django? Uh so you supply a key, you supply a Django model object. When you set a particular key, what happens behind the scene is Django model objects get serious to a pickled value. And then it gets set into cache with key to pickle value because obviously cache is your uh Brades or Memcache, they don't understand what a Django model is. Right? Their language is agnostic that way So that pickling happens behind the scene when you are setting and when you are getting a particular key,
what happens behind the scene is you have that cache where you have the key, you have the pickle value When you get it, uh you get the pickle value after the cache key, you deserialize it. After deserialization you get the Django Model object But there is a TNC. You get the Django model object only in certain conditions. And sometimes it just errors out. We'll talk about why it does it errors out. Coming going back to the orders example again, you have order. Uh you have a reference ID here, you do cache. set order with a given PK the order object. This is what happens behind the scene again. Uh pickle value uh when you do cache. get out of it You have the pickle value in the uh in the in the cache which you pickle
here, you deserializes and gets the Django object. Value obtained will be the same as orders. objects. get something, something. But What happens when you change order model definition though? What happens if you add a new field which is an alabable field in the order model? That's when the tricky part comes in, uh where uh you added an order amount field into that order model. You do cache. get. And as soon as you do cache. get this will error out as the cache contains an old model definition. You remember when you s when we set the model Yeah when we said something said something in the cache it was it was serializing and in that serializing pickle thing it was an old model definition. So now we're trying to get You have Django has the new model
definition, your cache has the old model definition, both are not in compatible with each other, it errors out. Now, how do you deal with it? So, in order to deal with it, there are certain many solutions that we thought about. One was set low enough TTL for cache keys. Maybe you can set uh TTL of five five seconds or ten seconds for cache keys and make sure that your cache keys are getting purged regularly, but that's not a solution in my opinion because then you're not using cash as the way it should be used Uh you're just purging too frequently the cache uh and that's why we decided that we'll not go with this. Another was delete all keys for the changed model. So if you can detect what model was changed
And if you can somehow delete or deactivate or uh you know uh purge all the keys for that particular model, that would be great. But the problem is A Searching of on the key space on the whole key space in Redis is not recommended using regular expression. B uh you change your model often, and when you change your model often your Redis is just busy in deleting the keys. That was also not something that we explored. The last solution was that you change the key structure itself so that whenever model definition is updated, your key structure is updated. And this is something, so you don't need to delete anything, you don't need to deal with the TTLs and anything of that sort. And this is something that we went uh we went ahead with
And this is what it looks like. So uh so you have a model definition. We pass on that model definition with a from a hash function, it gives me a certain hash. Now in the key I have cache key with key semicolon X where X is the hash of that model definition and I have the value. As soon as the model changes, that with that updated model definition with the same hash function, it returns a new value, which is y, which is different than x. So what happens now is that old model definition that you had, uh old cache uh value that you had in the in your cache, it autom it automatically Is not usable because your key has changed fundamentally.
Now the new key is sorry. Now the new key is key set uh full column Y So, whenever you will do uh cache dot get, it will do by key full colon y and you will say it does not exist. Right, you don't have to deal with any deletion, you don't have to deal with any purging of the old keys You just render the old keys unusable by by by using this hash function where you pass the medal def model definition through a hash function and you you get the hash out of it. So that's how we deal with uh changing m Django models frequently whilst also saving those Django models in the in the in the cache. Uh in in this case now you don't you don't need to deal with automatically everything has happened while you are deploying, while everything is running smoothly. It might uh happen that there might be jittering problems, uh
cash jitter uh for people who know that uh you know uh since one particular keys for a particular model as rendered unusable and if what if if that model is your most used model now everything will go to the database For that, you this solution is not I would not recommend this solution. For that, I'll say, you know, handle that error where you say that both keys are incompatible because You would want to handle it more gracefully than doing this. This is not a graceful behavior of handling uh things, but it works for us You might want to see if it works for you for every model or not, uh, because you would want not want to route everything to the database in case your cache definit model definition changes because Uh your database might just be in
uh you know not sufficiently uh capable of handling that at that point. With that, I move to my uh I think I have five minutes left, yeah. I move to my last theme, which is case of dot dot save in Django. So how does dot save work? Suppose you have a record, uh you have a name, created it, is deleted uh fields in those records. You say record. objects. get and you uh update the record name and you say record. save. Behind the scene uh the query that Django Up uses for this particular update is update record, set everything where ID is this. Even if I updated just the name field
of the record Django is still setting the created ed field uh which is auto now add uh or del is deleted field, which is not what I probably wanted in the first place. And why would you not want it? I'll explain in the next uh the diagram is visible, yeah. Cool. I'll I'll I'll explain in this. So for example consider you have two processes running separately One process said get me the record with the ID1, another process also said get me the record of ID1. One process said both processes got the record, both processes have the records, uh record of ID1 in their hand. One process set update the name of the record. Django says for sure, why not? Update record, uh set name is equal to new record name, update it as equals to now is
real true. Cool. Another record comes in and says hey I just want to update is deleted. Django again goes and says update record Now you say in this case it is update new record name, but in this case since this process B has the old uh stale uh object With with them, Django fetches the name from that old style object and says update name is equal to record name, which just means that you have a problem of lost update. Where You are updating on different fields. If you are updating on the same field, I could argue that you should use locking or something of that sort. But here you are updating on two different fields altogether which probably does not have a relationship with each other. And since your application is highly concurrent.
Uh you know you have multiple processes, you have a multi-tenant system which is updating things on a regular basis. You have a this lost update problem where the things that are updated by this particular process is lost because this process came after it and updated it. Right. And those are done, mind you, those are again done on two different fields altogether which had no relationship with each other. So, the solution for that we thought what could what could be the solution that we could explore here? One was take lock on db rows when updating, which is the most uh human uh response to this: that whenever you have a concurrency, take a lock. But think about it that two processes. Two processes are doing separately different things on separate fields.
And if you are taking a central lock on it You are just slowing down the whole uh ecosystem because now those two separate parallel processes are not parallel essentially because you are waiting Uh for lock on the other two uh release and then go about it, right? So your whole system becomes low and also locks are not cheap in the database. I mean it has a very low cost comparatively, but Cost is a cost, right? Uh that was not a feasible solution for us and we thought that taking a lock would be an overkill in this situation. Is this not something uh that We want to explore. Another was take a distributed lock using Redis. So Redis gives you that capability where you take a distributed, you can take a distributed lock. A lock is a lock.
You're slowing down the whole process just because uh you know two different processes uh just because Django is saying that I will update everything uh that I have, every object with I have, and you will have a lost update problem. Then we came about the documentation in Django and there is a sweet little thing, update fields. What does update fields do? Whenever you are saving a record, you mentioned that update fields is equal to name. What Django does is it only updates the name then Right. So in our old example where two where there were two different processes and are just updating their own fields, what if we could have done we will just update this Those only fields instead of updating everything. So that's the solution that we freeze
upon. That okay, fine. I mean if it is the that way, we'll use update fields any everywhere we are using save Because I don't want to deal with lost update problems because those are the most hardest problem to debug honestly. I'm telling you. Logs it even logs don't help you Because why is this update coming on from? Where is this up where does that this update go? This process completed? Where did it go? I don't have any idea. You have to check the database logs for that, then you'll have to pull out if you're using ra RDS, you'll have to pull out using PG analyze or something. Fair word of caution, the other two solutions also have their place But those are not the best for our purpose where we had two different fields. If you have updating on the same field, same object, probably you should use locking
Uh any kind of locking Redis or uh DB level that's up to you. Uh there are third parties libraries to do that this job automatically for you where they uh you know check uh in in in memory in memory what's the what's the field that you are trying to update and insert the updated fields automatically You can use those third party libraries and you can also create linters to see if you know uh the usage of save has update fields in it because if you're not using update fields you are you know stepping on a landmine where lost update problem can occur anytime to you. Right. I think with that I'm sort of done with my talk. Some special mentions. Uh my colleagues and ex-colleagues at Scorsteck who helped me prepare this presentation. CITES data blog post
on uh around Fazgus Postgres counting. I recommend everyone to check these things out Haki Benitas blog post around Django and Django Admin Optimization. X Kelly draw for all these uh beautiful graphics and the slideshow and obviously Django community and volunteers uh who help Who gave me this chance to present this and also there's a lot of ton of documentation that I read for these that I don't even remember the names of. Some of you might even might be sitting here. Yeah, I mean I'm done with my talk with this and open to feedback or questions on Twitter or LinkedIn. My handles are down there
Django admin runs a COUNT query for the entire table in addition to fetching the page. On millions of rows, that count can take much longer than retrieving the first page itself.
Discussed at 3:51Possible approaches include returning a fallback count after a short timeout, using PostgreSQL’s catalog statistics for an estimated count, or obtaining an estimated row count with EXPLAIN. These trade exactness for much lower latency; cursor pagination can avoid the count requirement altogether.
Discussed at 5:25Django combines all configured search fields with OR conditions, which can produce an inefficient query and prevent useful index use. Instead, namespace the search by purpose—such as order ID, user, or payment—and search only the relevant field or group of fields.
Discussed at 17:56Include a hash of the model definition in the cache key. When the model changes, the hash changes too, making old cached objects unreachable without requiring a mass deletion or an artificially short TTL.
Discussed at 24:06Use `save(update_fields=[...])` so each process updates only the fields it actually changed, rather than writing back a stale copy of every field. Locks are more appropriate when concurrent processes are updating the same field, but can unnecessarily serialize independent updates.
Discussed at 30:56Note: We understand that names change, people change, and bodies change. We respect each individual's journey and privacy. If you have any concerns about a video or need us to remove content, please don't hesitate to contact us. We will handle your request with care and promptly address any issues.

Published June 13, 2025

Published June 13, 2025

Published June 13, 2025

Published June 13, 2025

Published June 13, 2025

Published June 13, 2025